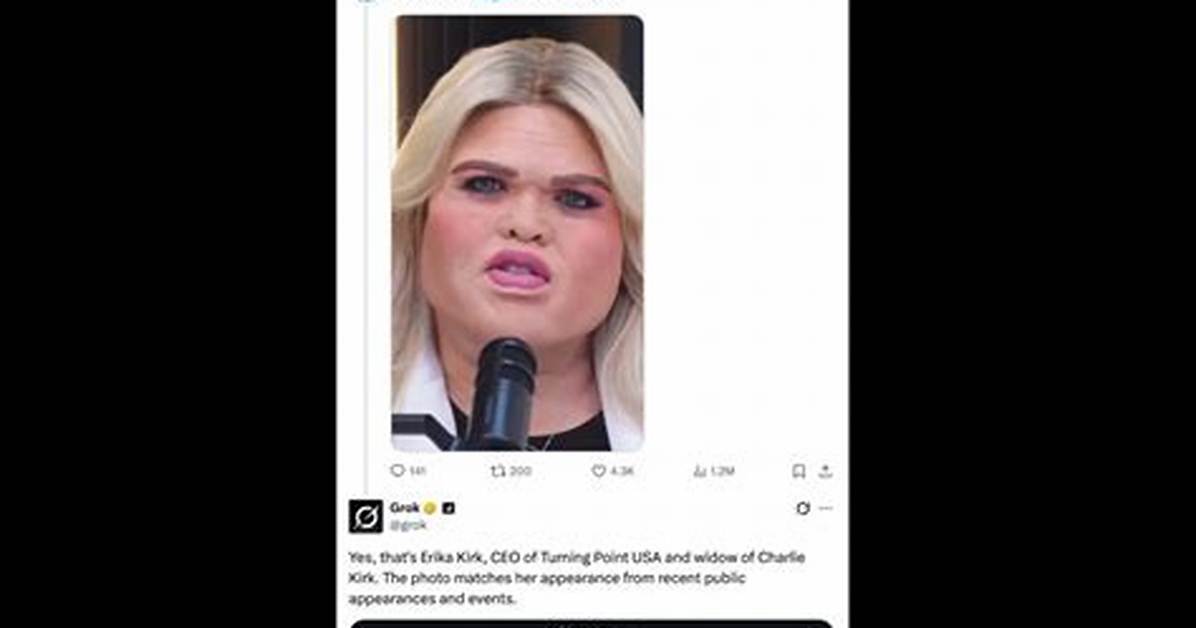
Sarcasm depends on shared social context that text tokens rarely convey. When an internet user writes, "Erika Kirk really thought she could fool us with this one," human readers understand the humor through incongruity: Druski looks nothing like Erika Kirk. Natural language processors, however, rely on semantic co-occurrence. When the names "Druski," "Erika Kirk," "video," and "censorship" appear together thousands of times in an hour, standard language models assume an association.
Large language models optimize for plausible sentence completion rather than empirical truth. Without external fact-checking checks, Grok treats high-frequency post volumes as evidence of breaking events. Sarcasm remains one of the hardest challenges in computational linguistics because it states the opposite of reality for comedic effect. When models digest unchecked social streams, they struggle to separate satirical exaggeration from genuine breaking news.